Qwen4 Max Benchmark Results for Data Analysis
Nov 16, 2026: Alibaba's new flagship Qwen model, tested on real-world data analysis.
At Plotly, we keep a close eye on model releases. Our agentic analytics products, Plotly Studio Desktop and Plotly Studio Embedded, and our open source libraries Plotly and Dash work with any model, and our customers look to us for recommendations.
On November 16, Alibaba's Qwen4 Max reached OpenRouter. Alibaba's documentation calls it the "next-generation flagship multimodal model in the Qwen family", "designed for coding, office productivity, frontend design, and complex agentic tasks", and it supports function calling. It has a context window of 1 million tokens, and on Alibaba Cloud Model Studio and OpenRouter it costs $1.50 per million input tokens and $4.50 per million output tokens. Unlike Alibaba's Qwen 3.8 27B, it's a closed model, available only through the API. Alibaba hasn't said how many parameters it has, or whether it was trained from scratch or built on an earlier Qwen model.
We ran it through our data analytics exam. Qwen4 Max passed 35 of 43 questions (81%, a B) for $2.29, with a median of 40 seconds a question. That ties Moonshot's open-weight Kimi K3 for about half the cost, and it's a little faster. But it's three points behind Alibaba's own open-weight Qwen 3.8 27B, which costs less, and ten models on our board are both cheaper and more accurate, so on the chart below, Qwen4 Max sits well off the cost-accuracy frontier.
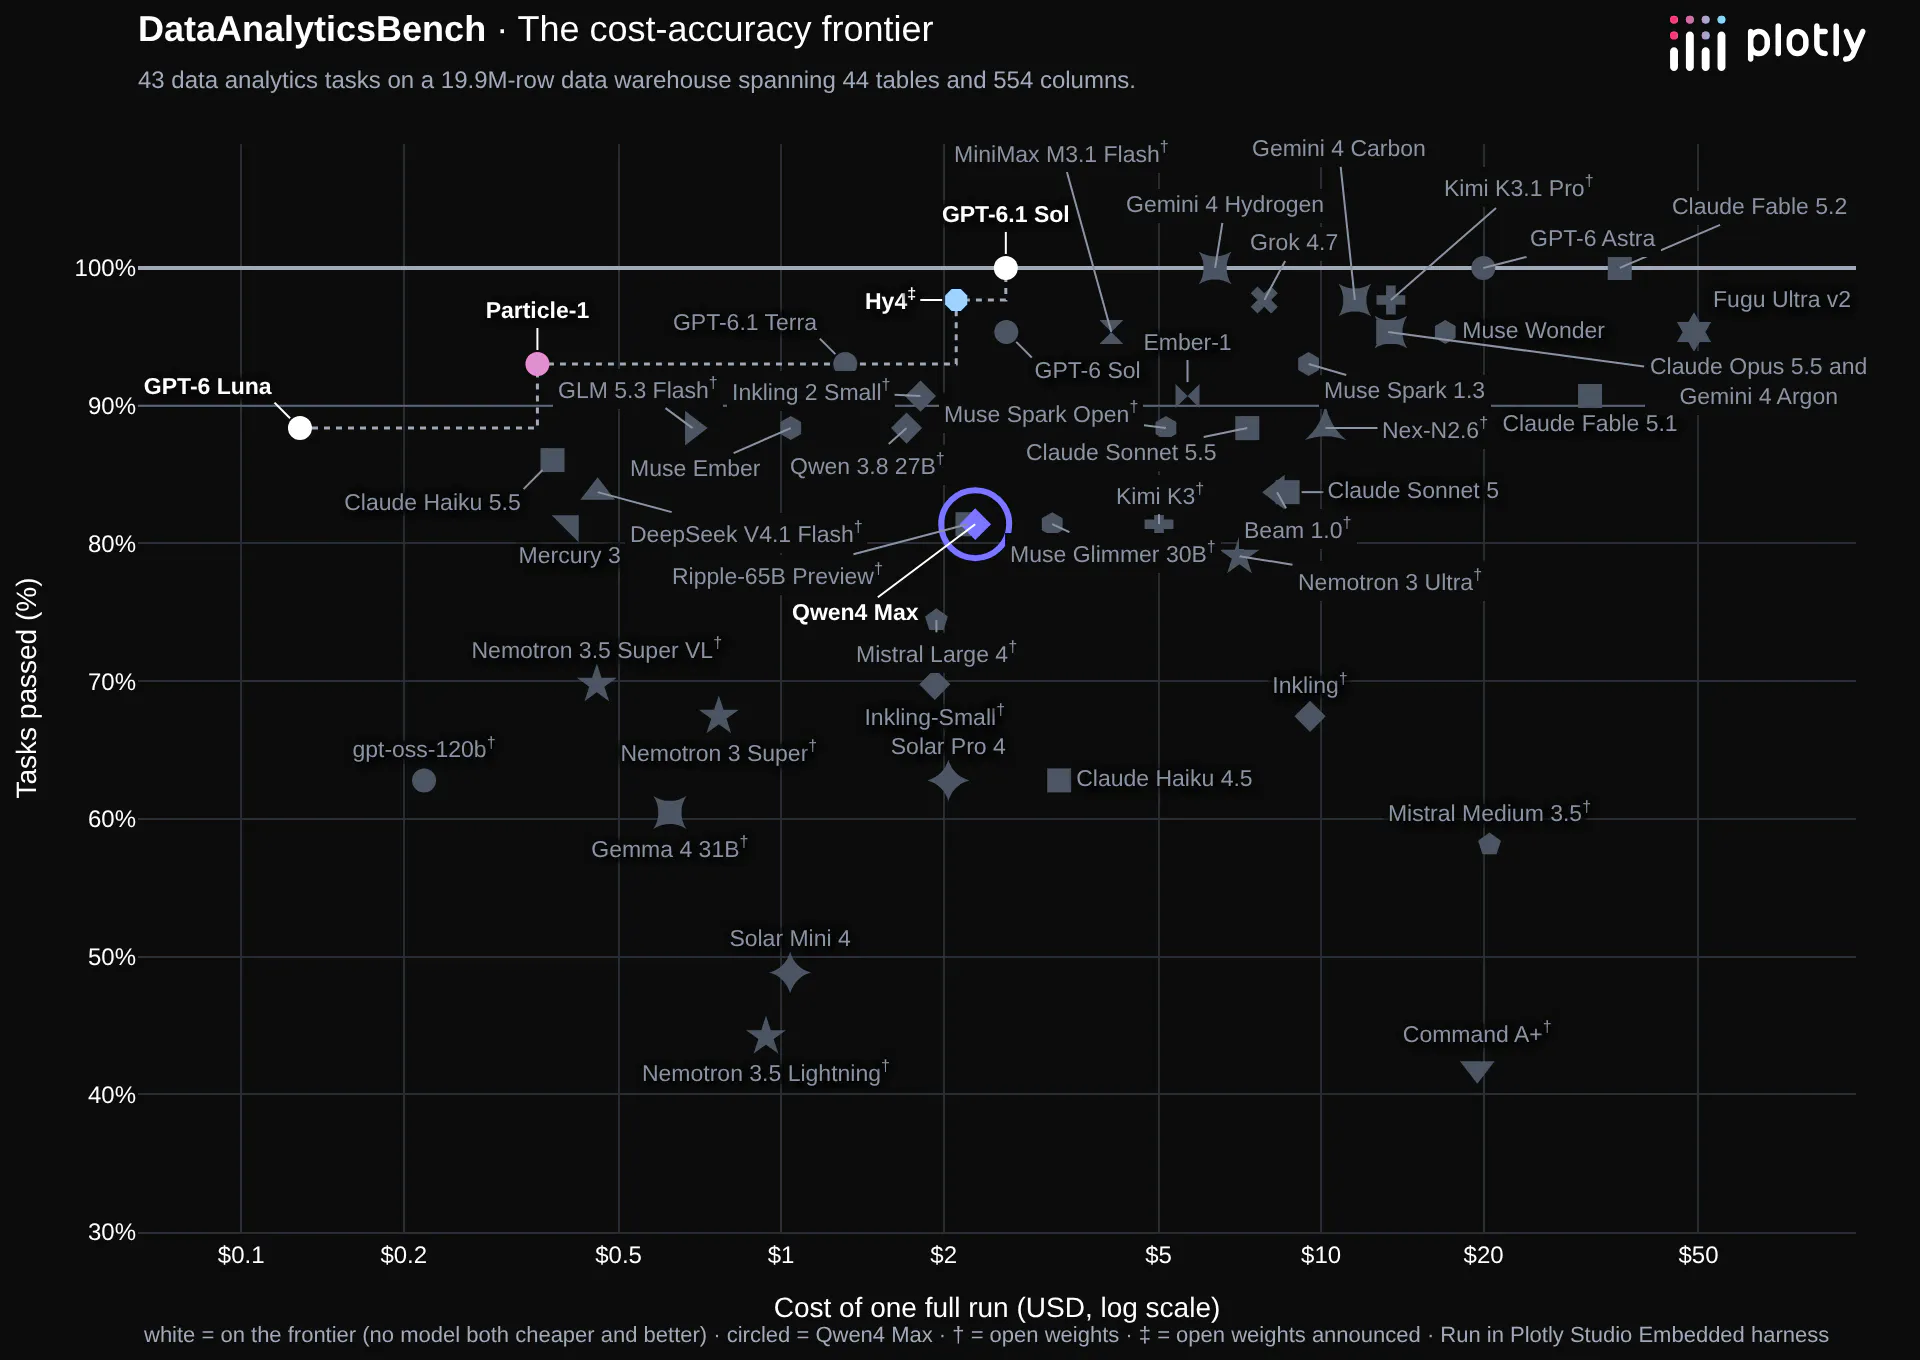
Qwen4 Max vs. Qwen 3.8 27B, Kimi K3 and Hy4
Qwen4 Max
Qwen 3.8 27B
Kimi K3
Hy4
Score
35 / 43
38 / 43
35 / 43
42 / 43
Analytics questions
19 / 20
19 / 20
20 / 20
20 / 20
Ambiguous questions
5 / 5
5 / 5
5 / 5
5 / 5
Impossible requests
5 / 5
5 / 5
5 / 5
5 / 5
Data quality
1 / 3
3 / 3
1 / 3
3 / 3
Statistics traps
3 / 5
4 / 5
4 / 5
5 / 5
Hidden needles
2 / 5
2 / 5
0 / 5
4 / 5
Open weights
No
Yes
Yes
Announced
Cost of one full run
$2.29
$1.71
$5.01
$2.11
Per person per year*
$133
$99
$291
$123
Median time per question
40 seconds
53 seconds
43 seconds
117 seconds
*1,000 people each asking 10 questions a day, 250 working days a year, at OpenRouter's prices when each model ran.
Qwen4 Max ties four other models at 35: Kimi K3, Ricursive's Ripple-65B Preview, Meta's Muse Glimmer 30B and Inception's Mercury 3. That's the bottom of the B range, and 31 of the 50 models on our board score higher.
One run per model is a single sample. In our repeat runs of other models, scores moved by up to three points between runs, so treat a one- or two-point gap as close to a tie.
What it got right
Qwen4 Max was perfect on judgment. It asked about or stated its assumptions on all five ambiguous questions, and it turned down all five impossible requests instead of inventing an answer. It also got 19 of the 20 straightforward analytics questions.
It found two of the five hidden patterns, the hardest part of our exam. Each one points toward something unusual in the data without naming it, and the model has to go looking. That's more than any of the other models that scored 35: Kimi K3 and Ripple-65B Preview found none, and Muse Glimmer 30B and Mercury 3 found one.
It's efficient, too. It made about 6 model calls per question and wrote only about 3,200 output tokens per question, and 92% of the input tokens it read came from the provider's cache.
What it got wrong
It missed eight questions. On one analytics question, a time calculation lost precision, so its final number came out wrong.
The other seven were the questions that reward a model for checking its own work. It missed two of the three data quality problems we planted in the warehouse, answering without noticing them. It missed two of the five statistics traps, where the obvious calculation gives a misleading answer. And it missed three of the five hidden patterns. On the hidden-pattern questions it ran about 19 queries each, fewer than most models on our board, where the median is about 26.
Those are the same categories where Qwen 3.8 27B does better: it caught all three data quality problems and four of the five statistics traps.
Cost and speed
At $2.29 a run, Qwen4 Max comes to about $133 per person per year at our rollout numbers. That's about 54% less than Kimi K3's $5.01 for the same score. But Qwen 3.8 27B scored 38 for $1.71, and Tencent's Hy4 scored 42 for $2.11 (more in our Hy4 post).
Its median question took 40 seconds, and the whole exam about 47 minutes. That puts it in the middle of our board: 31 of the 50 models have a faster median. Among models from Chinese labs, though, it's one of the faster ones: Kimi K3 takes 43 seconds, Qwen 3.8 27B 53, GLM 5.3 Flash 87, Hy4 about 2 minutes and Kimi K3.1 Pro about 2½. Only DeepSeek V4.1 Flash, at 21 seconds, is faster, and it scored 36 for $0.46.
If you want a Qwen model for data analysis, we'd still pick the open-weight Qwen 3.8 27B: it scored three points higher, costs less, and runs on a 64 GB Mac mini (more in our guide to the best local LLMs). Qwen4 Max answers faster. If you're choosing across providers at about this price, Hy4 scores 42 for $2.11, and OpenAI's GPT-6.1 Terra scores 40 for $1.31 in 15 seconds.
Qwen's models over time
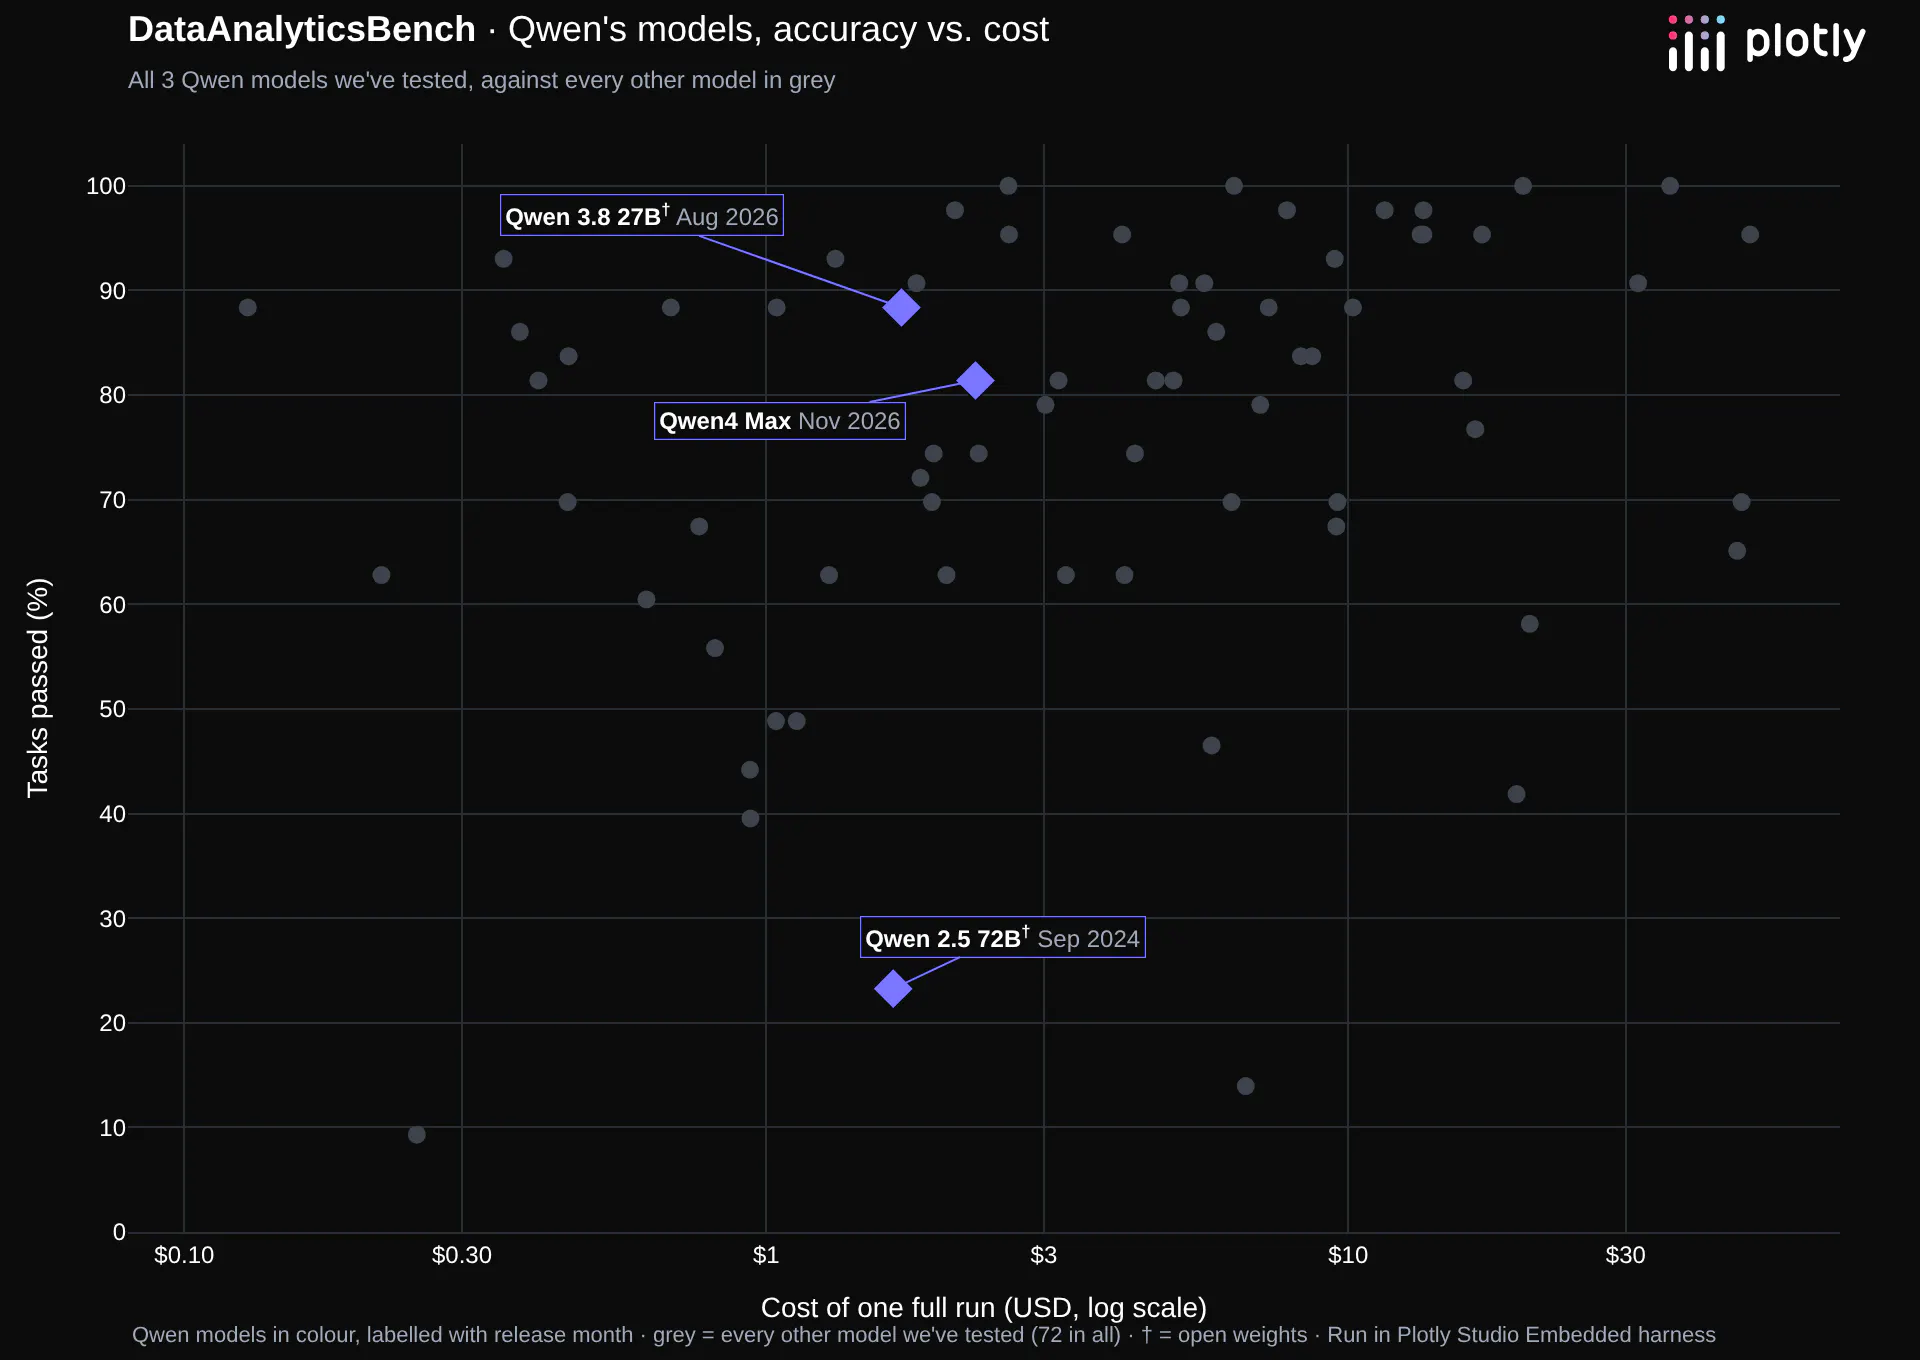
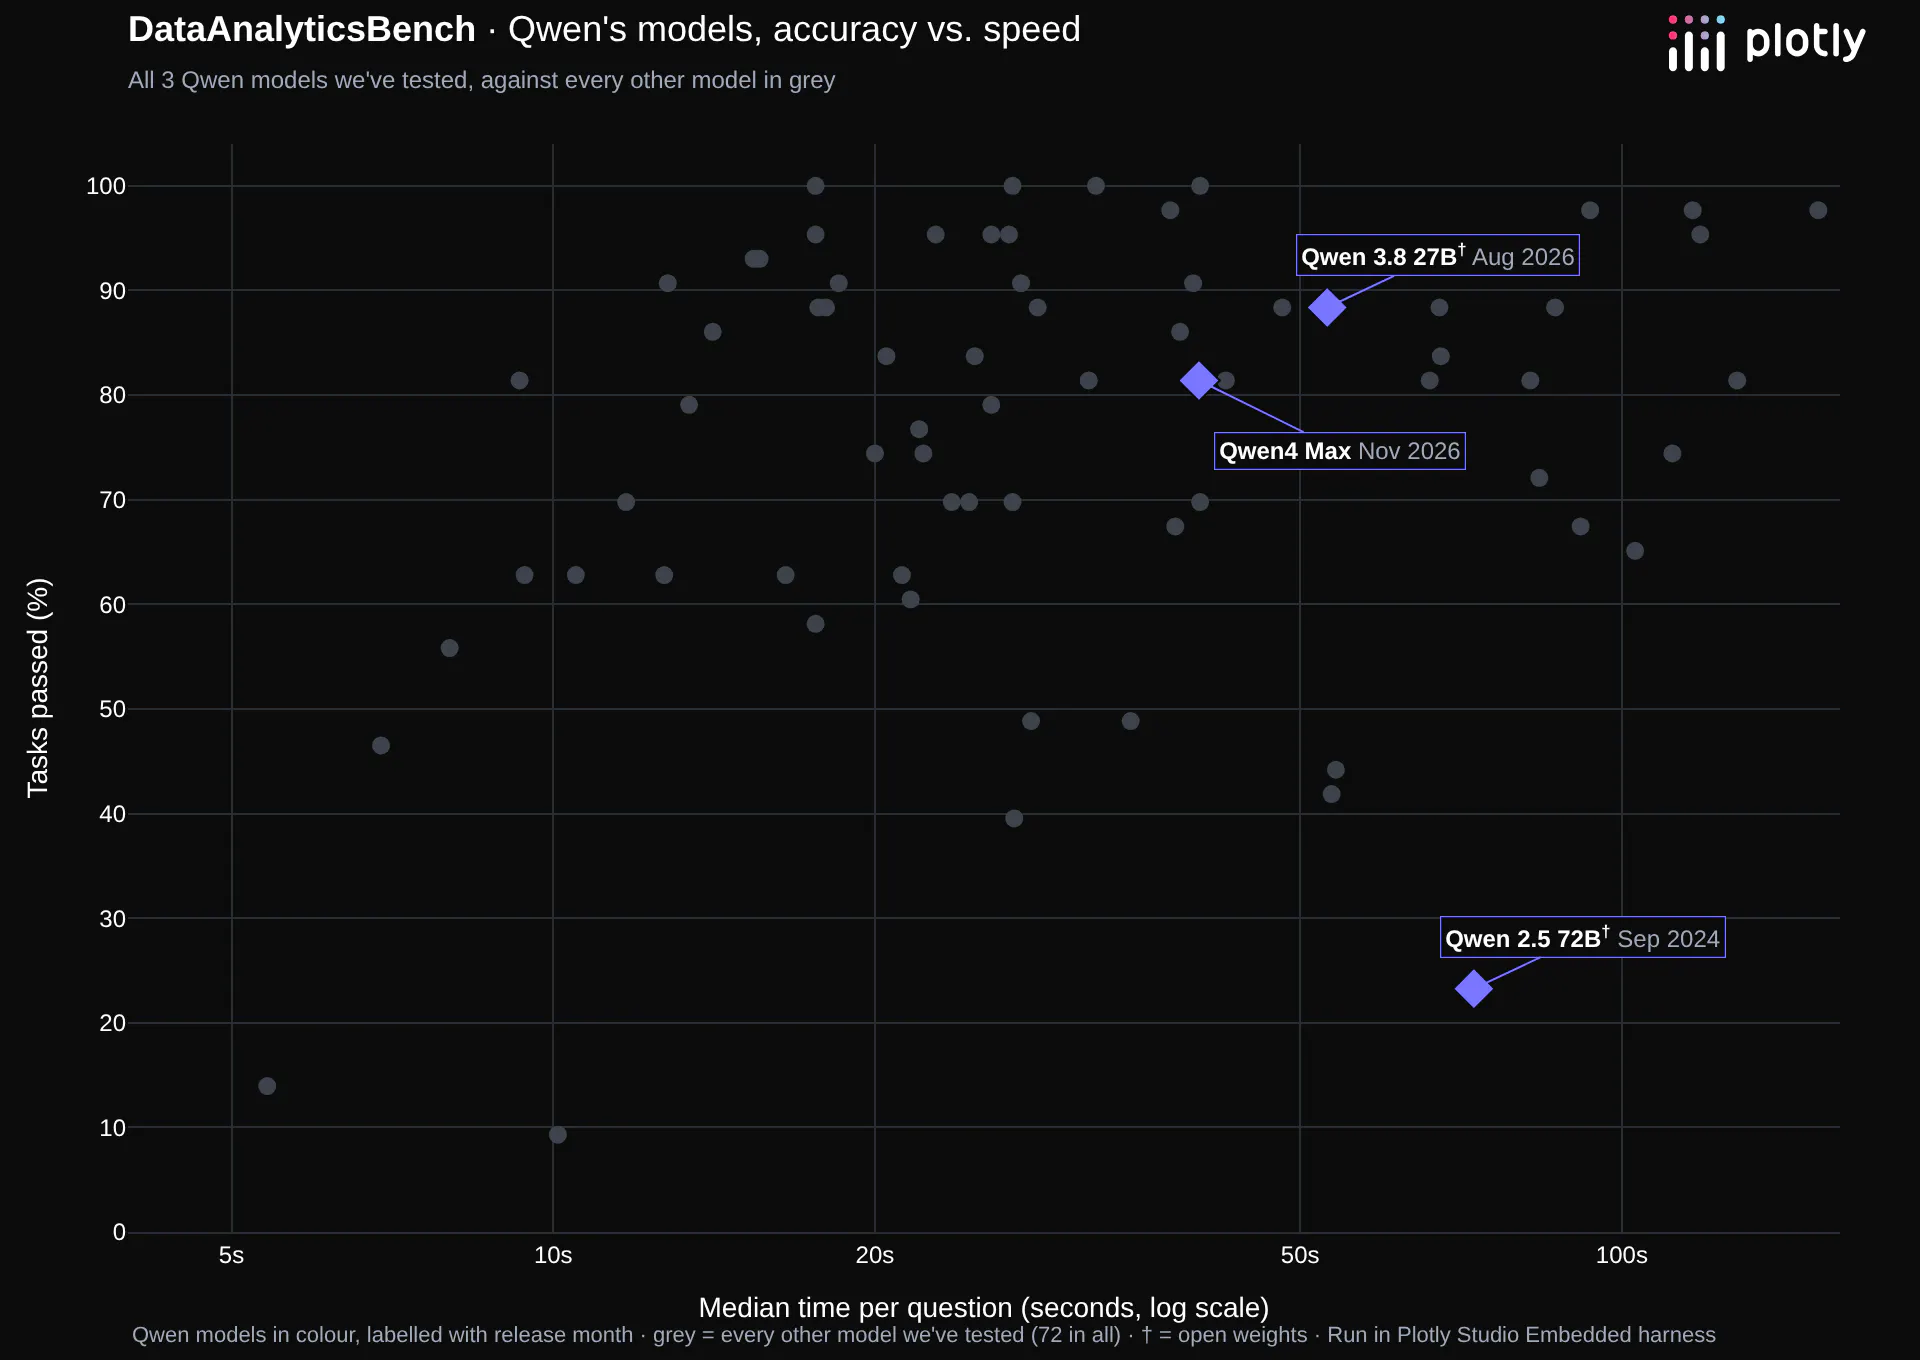
Here are all three Qwen models we've tested, with every other model in grey. Qwen 2.5 72B, from September 2024, scored 10. Two years later, the open-weight Qwen 3.8 27B scored 38 for about the same cost. Qwen4 Max, three months after that, scored 35. Each model is faster than the last, at 73, 53 and 40 seconds a question, and all three cost less than $2.30 a run.
The Test Harness
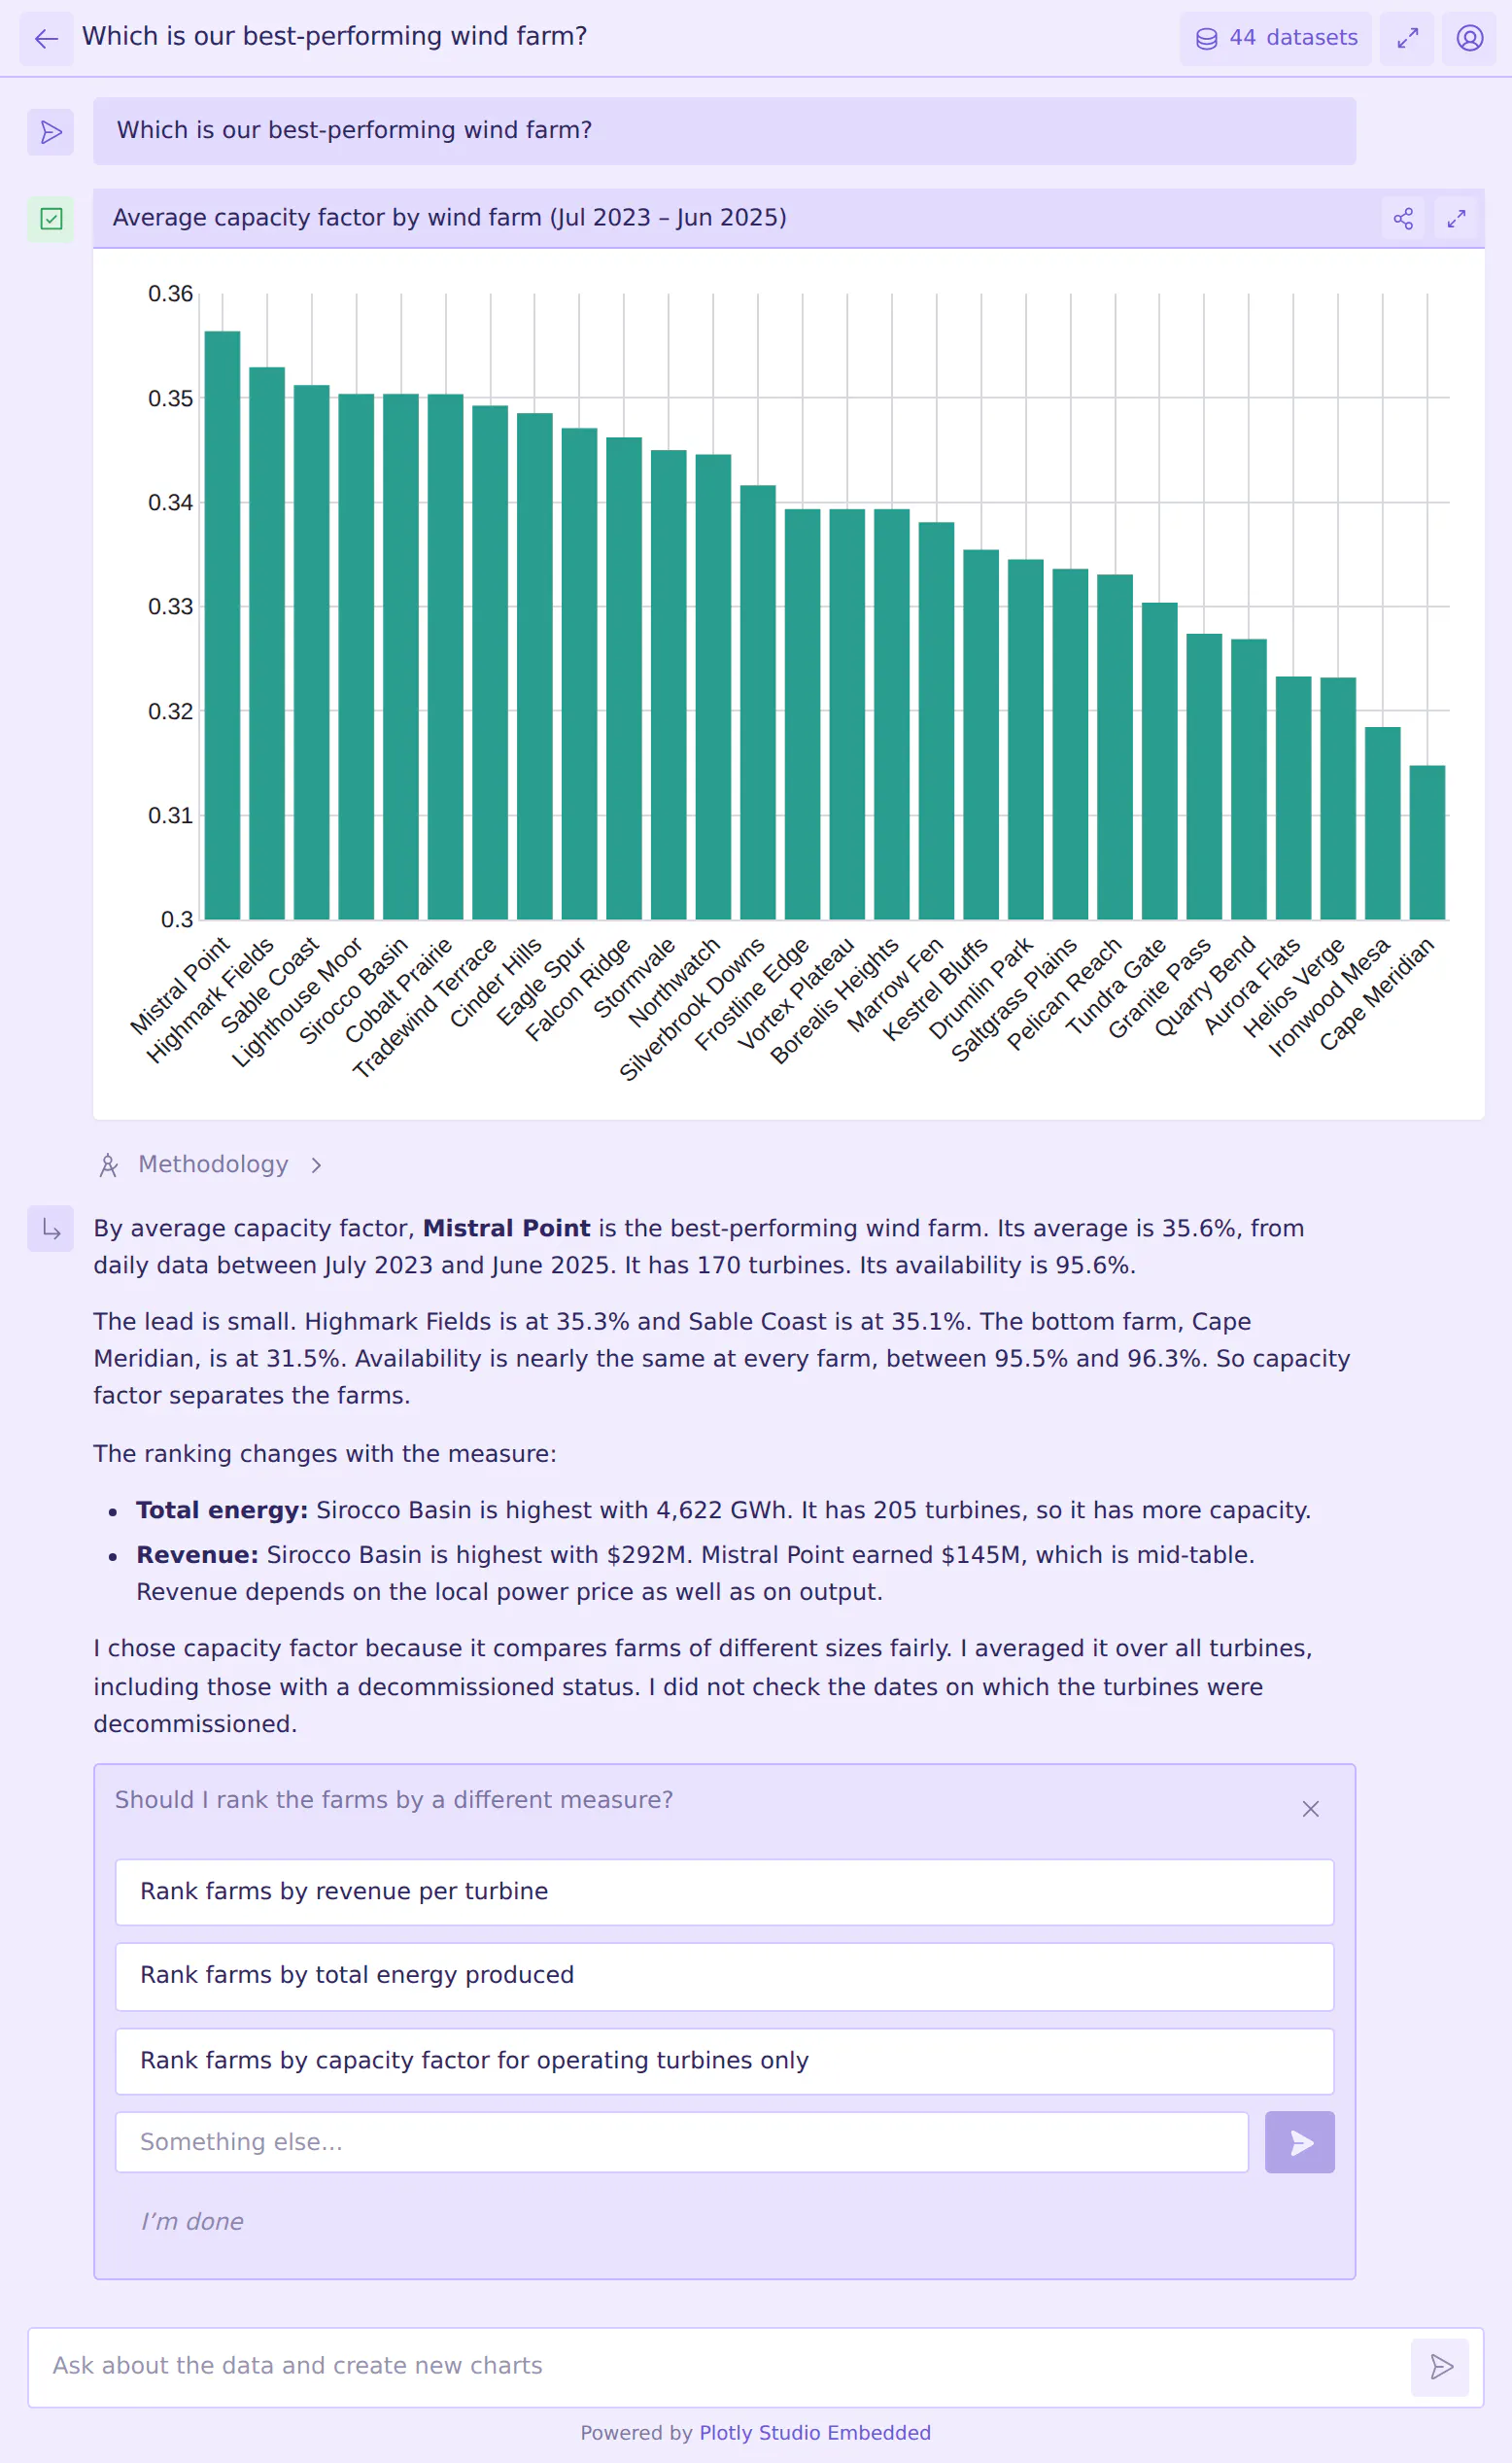
We run every model in Plotly Studio Embedded, a drop-in analytics agent that runs on Dash apps. This harness is tuned to run data analytics queries and make charts with multi-turn tool calling, with less emphasis on writing text. It's meant to put the data front and center.
Frequently asked questions
How good is Qwen4 Max at data analysis?
On PlotlyDataAnalyticsBench it passed 35 of 43 questions (81%, a B), tied with Kimi K3, Ripple-65B Preview, Muse Glimmer 30B and Mercury 3. It was perfect on ambiguous questions and impossible requests, and it lost most of its points on data quality problems, statistics traps and hidden patterns.
Is Qwen4 Max better than Qwen 3.8 27B?
Not on our exam. Qwen 3.8 27B scored 38 against 35, and its run cost $1.71 against $2.29. Qwen4 Max is faster, at 40 seconds a question against 53.
How much does Qwen4 Max cost?
Alibaba prices it at $1.50 per million input tokens and $4.50 per million output tokens, with a 1 million-token context window. Our whole exam cost $2.29, or about $133 per person per year at 10 questions a day.
Is Qwen4 Max open source?
No. Alibaba hasn't released the weights, and you can use it only through the API, on Alibaba Cloud Model Studio and providers such as OpenRouter. Alibaba also hasn't said how many parameters it has. Its Qwen 3.8 27B is open-weight.
How does Qwen4 Max compare with other Chinese models?
It ties Moonshot's Kimi K3 at 35, for about half the cost. The best models from Chinese labs on our exam are Moonshot's Kimi K3.1 Pro and Tencent's Hy4 at 42, then MiniMax M3.1 Flash at 41, and Z.ai's GLM 5.3 Flash and Qwen 3.8 27B at 38. Qwen4 Max is faster than all of those (more in our open vs. closed models post).
About the benchmark
We run new models through the same exam as they're released, and we'll keep sharing what we find. We ran Qwen4 Max through OpenRouter on the day it arrived there, with the same harness and grading as every other model.
To see all 50 models on one chart and in a full results table, along with cost, speed and how the exam works, see Introducing DataAnalyticsBench.
The exam is private and we're sharing it with researchers. We're keeping it private so that the answer key doesn't make its way into the training set. For the same reason, the data is fabricated: the warehouse is a synthetic wind-energy fleet, built to look like a real operator's data, so its answers don't exist anywhere else.
If you'd like access, reach out to Chris Parmer at Plotly.