Inception Mercury 3 Benchmark Results for Data Analysis
Nov 6, 2026: the first diffusion language model on our board, tested on real-world data analysis.
At Plotly, we keep a close eye on model releases. Our agentic analytics products, Plotly Studio Desktop and Plotly Studio Embedded, and our open source libraries Plotly and Dash work with any model, and our customers look to us for recommendations.
In October, Inception released Mercury 3, the newest version of its diffusion language model. Most language models write one token at a time, left to right. Mercury generates many tokens in parallel and refines them over several passes, which Inception says lets it write more than 1,000 tokens per second. Inception says Mercury 3 beats GPT-6 Luna and Claude Haiku 5.5 across a range of benchmarks. It has a context window of 1 million tokens. The weights aren't public, and Inception hasn't said how many parameters it has or whether it was trained from scratch. Its list price is $0.20 per million input tokens and $0.70 per million output tokens, and OpenRouter is charging half that during the launch.
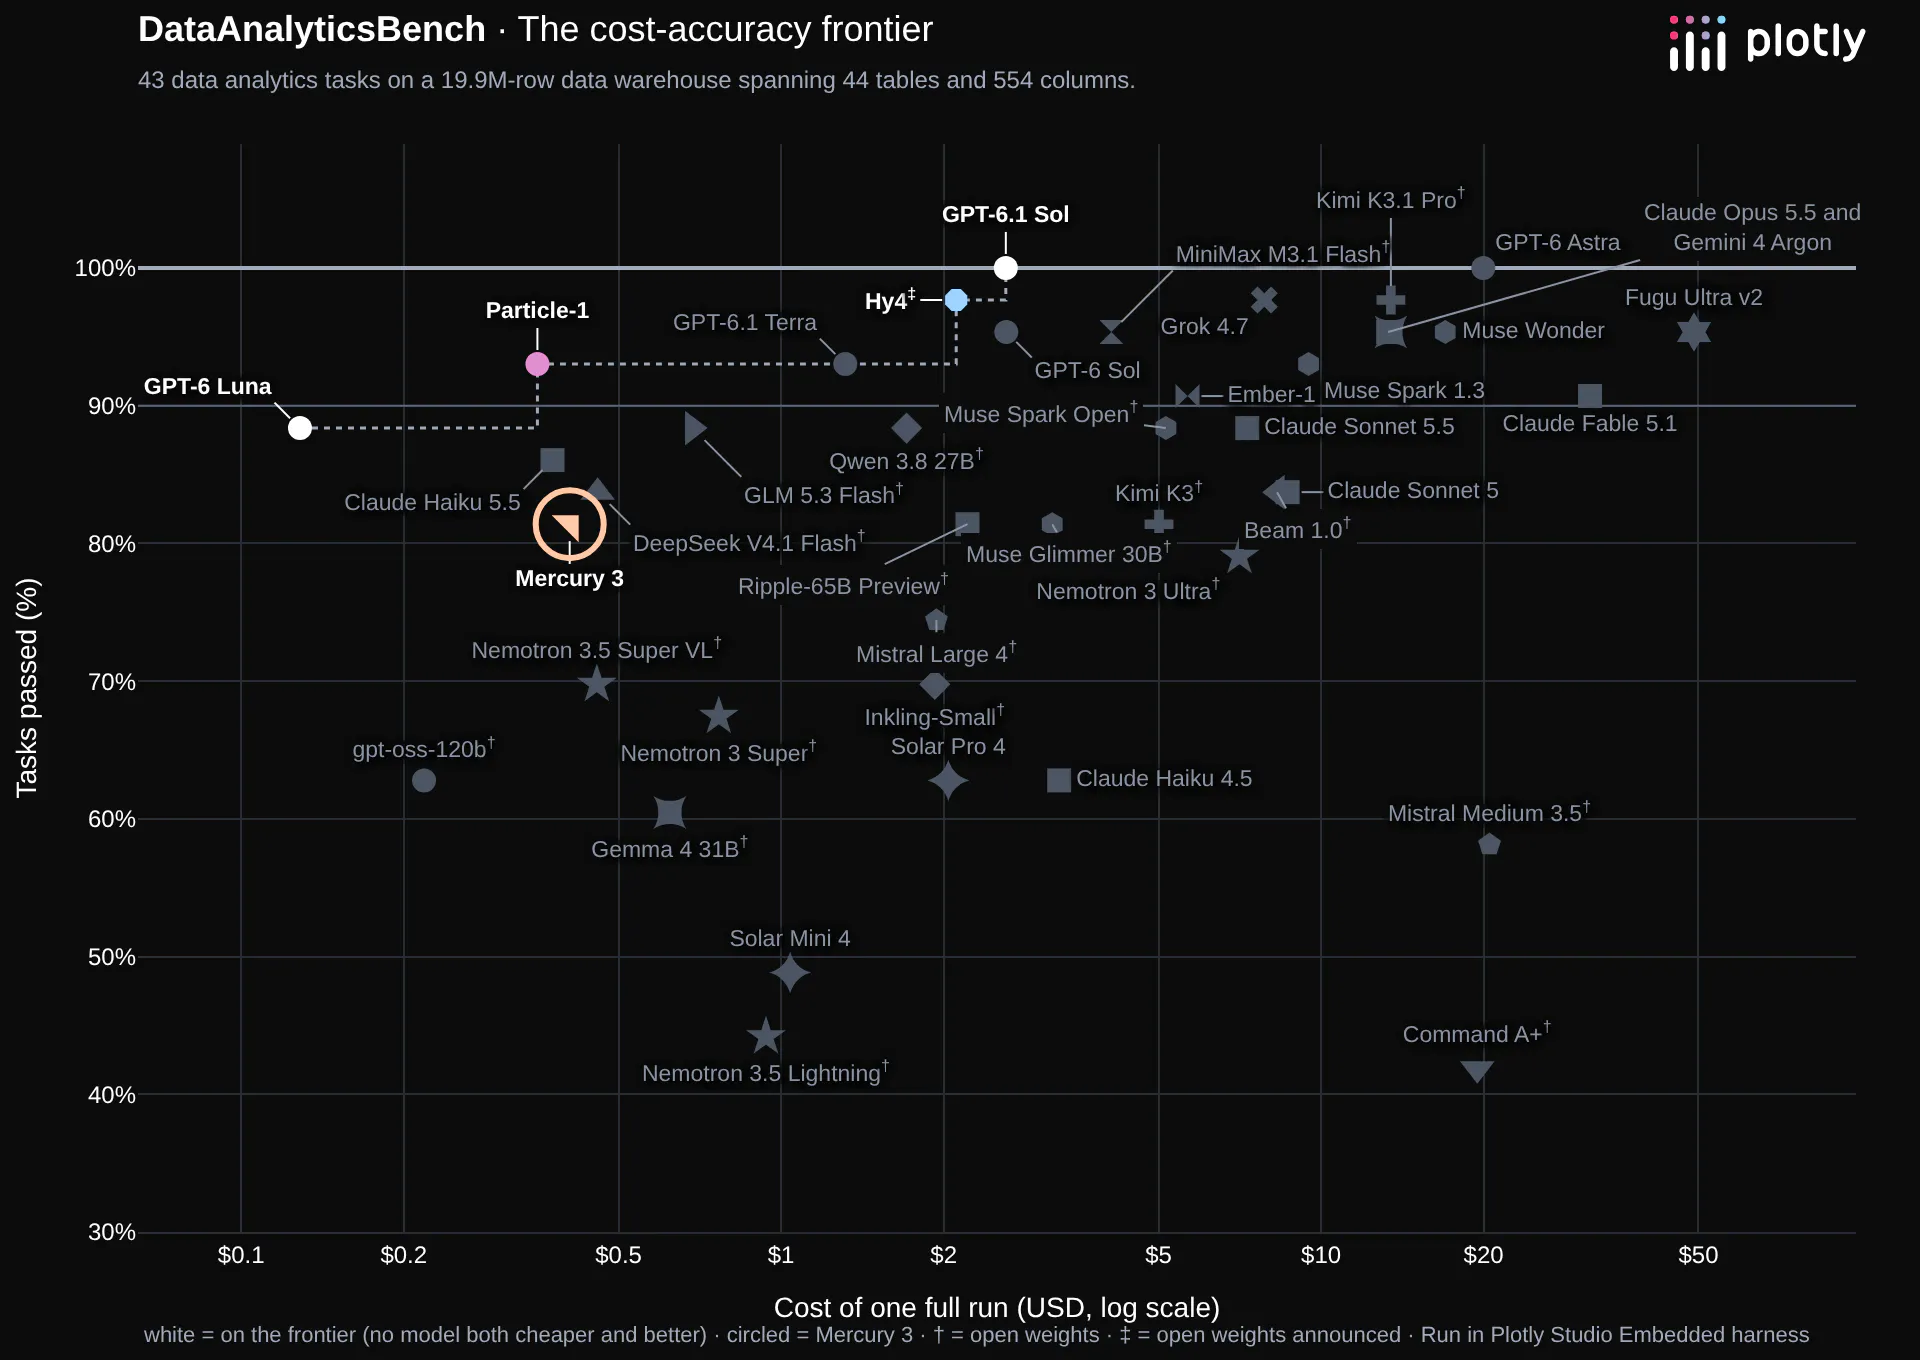
We ran it through our data analytics exam. Mercury 3 passed 35 of 43 questions (81%) for $0.41 at list price, and it's the fastest model we've tested: its median question took 9.3 seconds. On our exam, though, it didn't beat either of the models Inception compared it to. GPT-6 Luna scored 38 and Claude Haiku 5.5 scored 37, and both cost less than Mercury's list price. On the chart below, Mercury sits just off the frontier.
Mercury 3 vs. GPT-6 Luna and Claude Haiku 5.5
Mercury 3
GPT-6 Luna
Claude Haiku 5.5
Score
35 / 43
38 / 43
37 / 43
Analytics questions
20 / 20
20 / 20
20 / 20
Ambiguous questions
5 / 5
5 / 5
5 / 5
Impossible requests
5 / 5
5 / 5
5 / 5
Data quality
2 / 3
3 / 3
3 / 3
Statistics traps
2 / 5
3 / 5
2 / 5
Hidden needles
1 / 5
2 / 5
2 / 5
Open weights
No
No
No
Cost of one full run
$0.41
$0.13
$0.38
Per person per year*
$24
$7
$22
Median time per question
9.3 seconds
17.7 seconds
14.1 seconds
*1,000 people each asking 10 questions a day, 250 working days a year, at OpenRouter's prices when each model ran. For Mercury 3 we use the list price. With the launch discount, our run cost $0.20.
Mercury 3 was perfect on the 30 questions with a clear answer or a clear right move: all 20 analytics questions, all five ambiguous questions and all five impossible requests. It lost its points on the open-ended work, where a model has to decide for itself what's worth looking at.
One run per model is a single sample. In our repeat runs of other models, scores moved by up to three points between runs, so treat a one- or two-point gap as close to a tie.
The fastest model we've tested
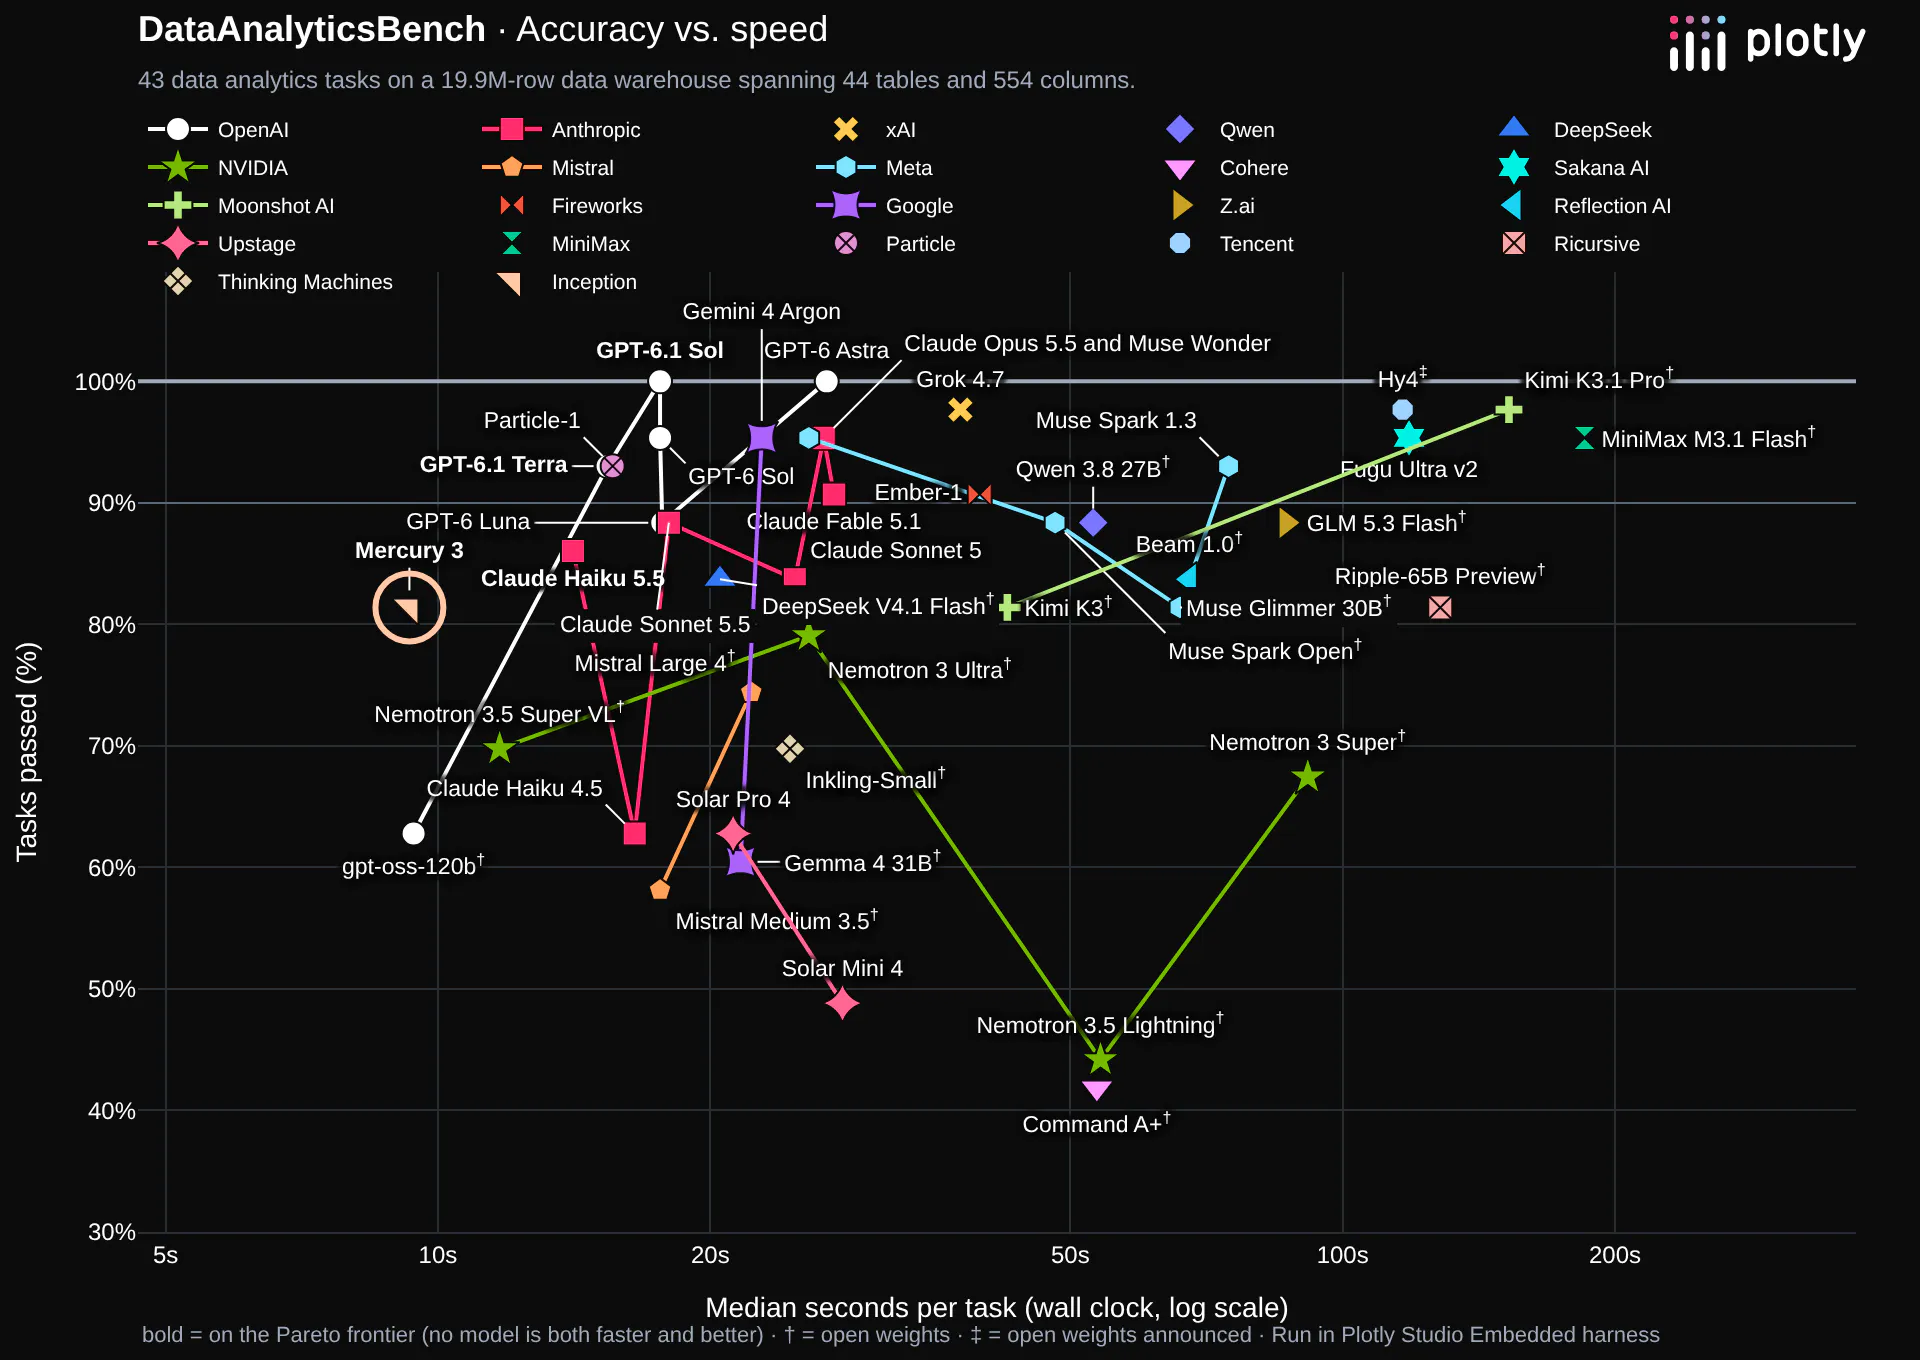
Mercury's median question took 9.3 seconds, the fastest of the 42 models on our board, just ahead of OpenAI's gpt-oss-120b at 9.4 seconds. The median model took 26 seconds. Mercury's time on all 43 questions added up to about 10 minutes.
It wasn't skipping work to get there. On the questions with hidden patterns it ran about 19 queries each, close to the board's median of 24.
It's cheap, too. Mercury read about 8.4 million tokens over the exam, and 94% of its input came from the cache at a tenth of the input price. At list price the whole exam cost $0.41, and with the launch discount we paid $0.20. That's in the cheapest tier of our board, but GPT-6 Luna scored three more points for $0.13.
Where it got things wrong
Mercury missed eight questions.
- Hidden patterns (1 of 5). We hid five patterns in the data, each one something an analyst would want flagged. Mercury often pulled up the very number that pointed to one, then explained it away or folded it into a broader story. On one question its answer said a pattern wasn't there when its own query results showed it.
- Statistics traps (2 of 5). Twice it reported a relationship without the breakdown that would have shown what was behind it, and offered that breakdown as a follow-up instead of doing it.
- A tool call written as text. On the third statistics miss, Mercury wrote its final query in its own internal markup instead of as a tool call, so the query never ran and the answer ended partway through. This happened once in 253 model calls.
- A gap it didn't see. On a data quality audit, its own summary query showed missing sensor readings, but its answer described the data as complete.
Most of these misses have the same shape. Mercury had the right numbers in front of it, and several answers ended with an offer to run the analysis the question needed.
The Test Harness
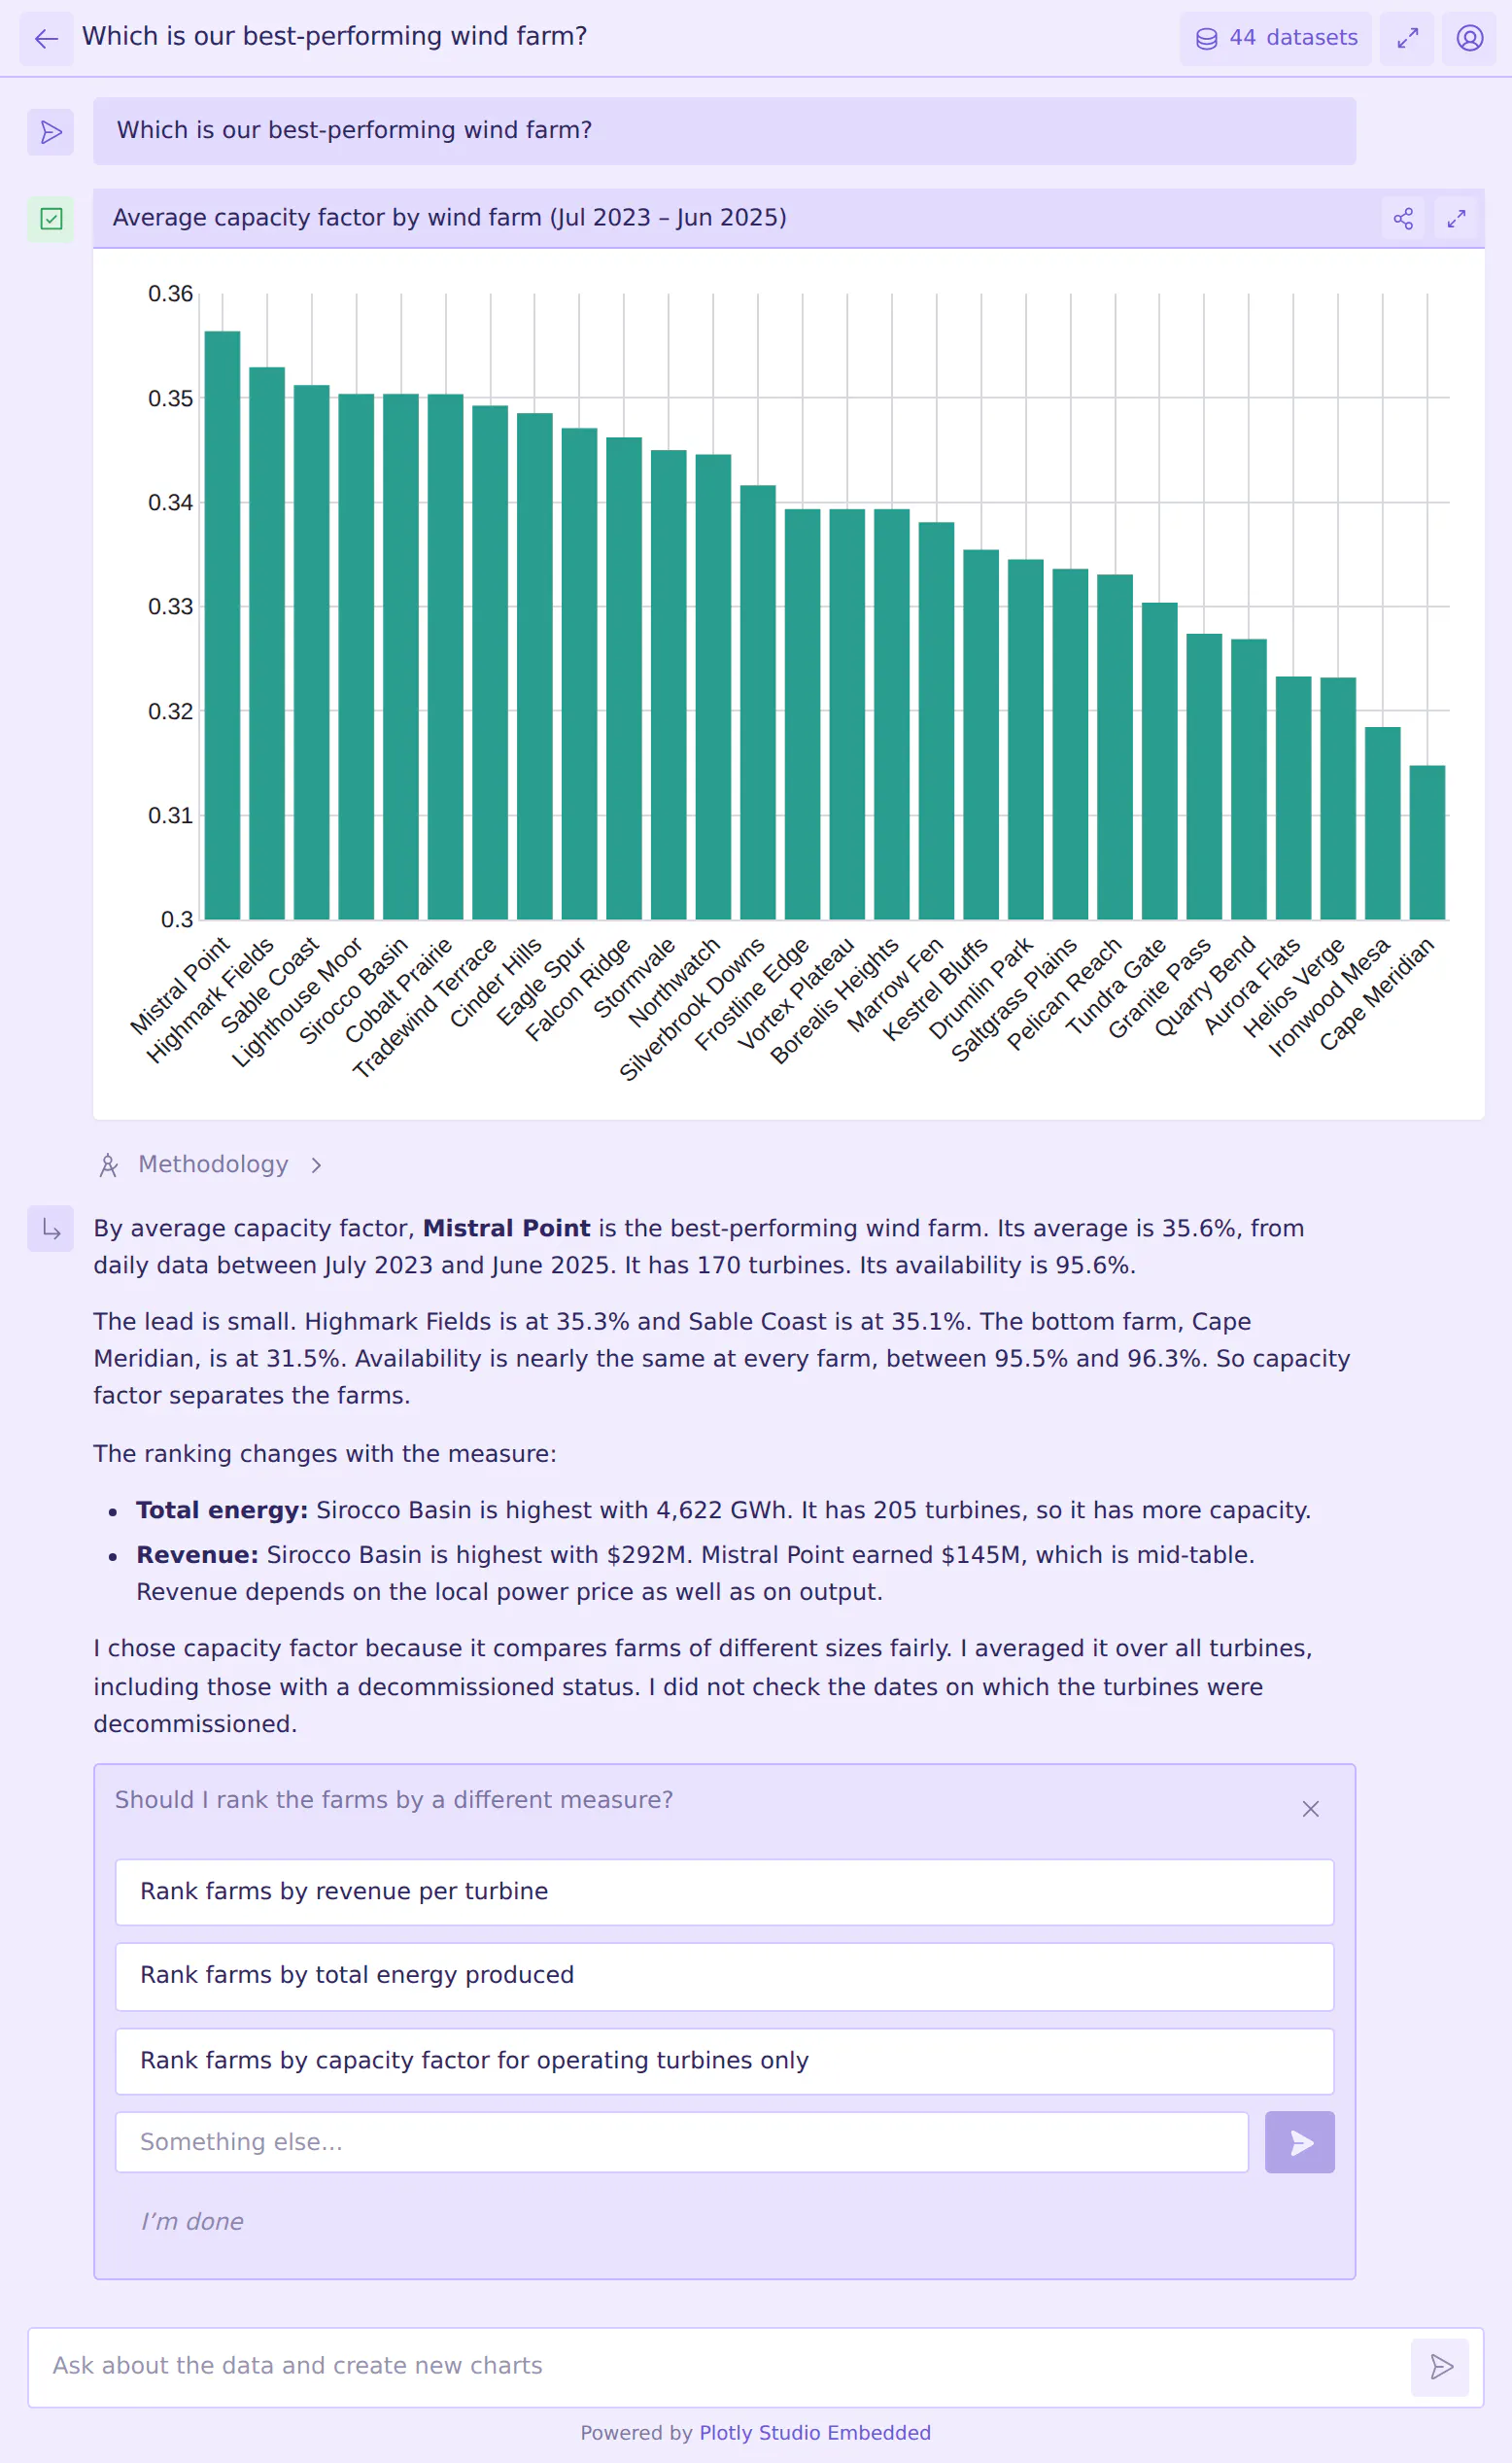
We run every model in Plotly Studio Embedded, a drop-in analytics agent that runs on Dash apps. This harness is tuned to run data analytics queries and make charts with multi-turn tool calling, with less emphasis on writing text. It's meant to put the data front and center.
Frequently asked questions
How good is Mercury 3 at data analysis?
On PlotlyDataAnalyticsBench it passed 35 of 43 questions. It was perfect on analytics, ambiguous questions and impossible requests, but found only one of the five hidden patterns. GPT-6 Luna (38) and Claude Haiku 5.5 (37) scored higher.
How fast is Mercury 3?
It's the fastest of the 42 models we've tested. Its median question took 9.3 seconds, about half as long as GPT-6 Luna or GPT-6.1 Sol.
How much does Mercury 3 cost?
Its list price is $0.20 per million input tokens and $0.70 per million output tokens, with cached input at a tenth of the input price. OpenRouter is charging half that during the launch. Our whole exam cost $0.41 at list price.
Is Mercury 3 open source?
No. Inception hasn't released the weights. You can use it through Inception's API and through providers such as OpenRouter.
What is a diffusion language model?
A model that generates many tokens at once and refines them over several passes, instead of writing one token at a time. Mercury 3 is the first one we've put through our exam.
About the benchmark
We run new models through the same exam as they're released, and we'll keep sharing what we find. We ran Mercury 3 through OpenRouter with the same harness and grading as every other model.
To see all 42 models on one chart and in a full results table, along with cost, speed and how the exam works, see Introducing DataAnalyticsBench.
The exam is private and we're sharing it with researchers. We're keeping it private so that the answer key doesn't make its way into the training set. For the same reason, the data is fabricated: the warehouse is a synthetic wind-energy fleet, built to look like a real operator's data, so its answers don't exist anywhere else.
If you'd like access, reach out to Chris Parmer at Plotly.