Meta Muse Ember Benchmark Results for Data Analysis
Nov 10, 2026: Meta's smallest Muse model, tested on real-world data analysis.
At Plotly, we keep a close eye on model releases. Our agentic analytics products, Plotly Studio Desktop and Plotly Studio Embedded, and our open source libraries Plotly and Dash work with any model, and our customers look to us for recommendations.
On November 9, Meta released Muse Ember, its smallest and most efficient model, built for the work agents repeat all day: tool calls, coding subtasks, routing, extraction and long documents. Meta says Ember delivers more intelligence per dollar than Claude Haiku 5.5 or GPT-6 Luna, and that it's the first model Meta trained using Muse Wonder Full. It reads text, images, audio and video, and it has a context window of 1 million tokens. Meta hasn't released the weights or said how many parameters it has. It costs $0.10 per million input tokens, $0.004 per million cached input tokens and $0.50 per million output tokens.
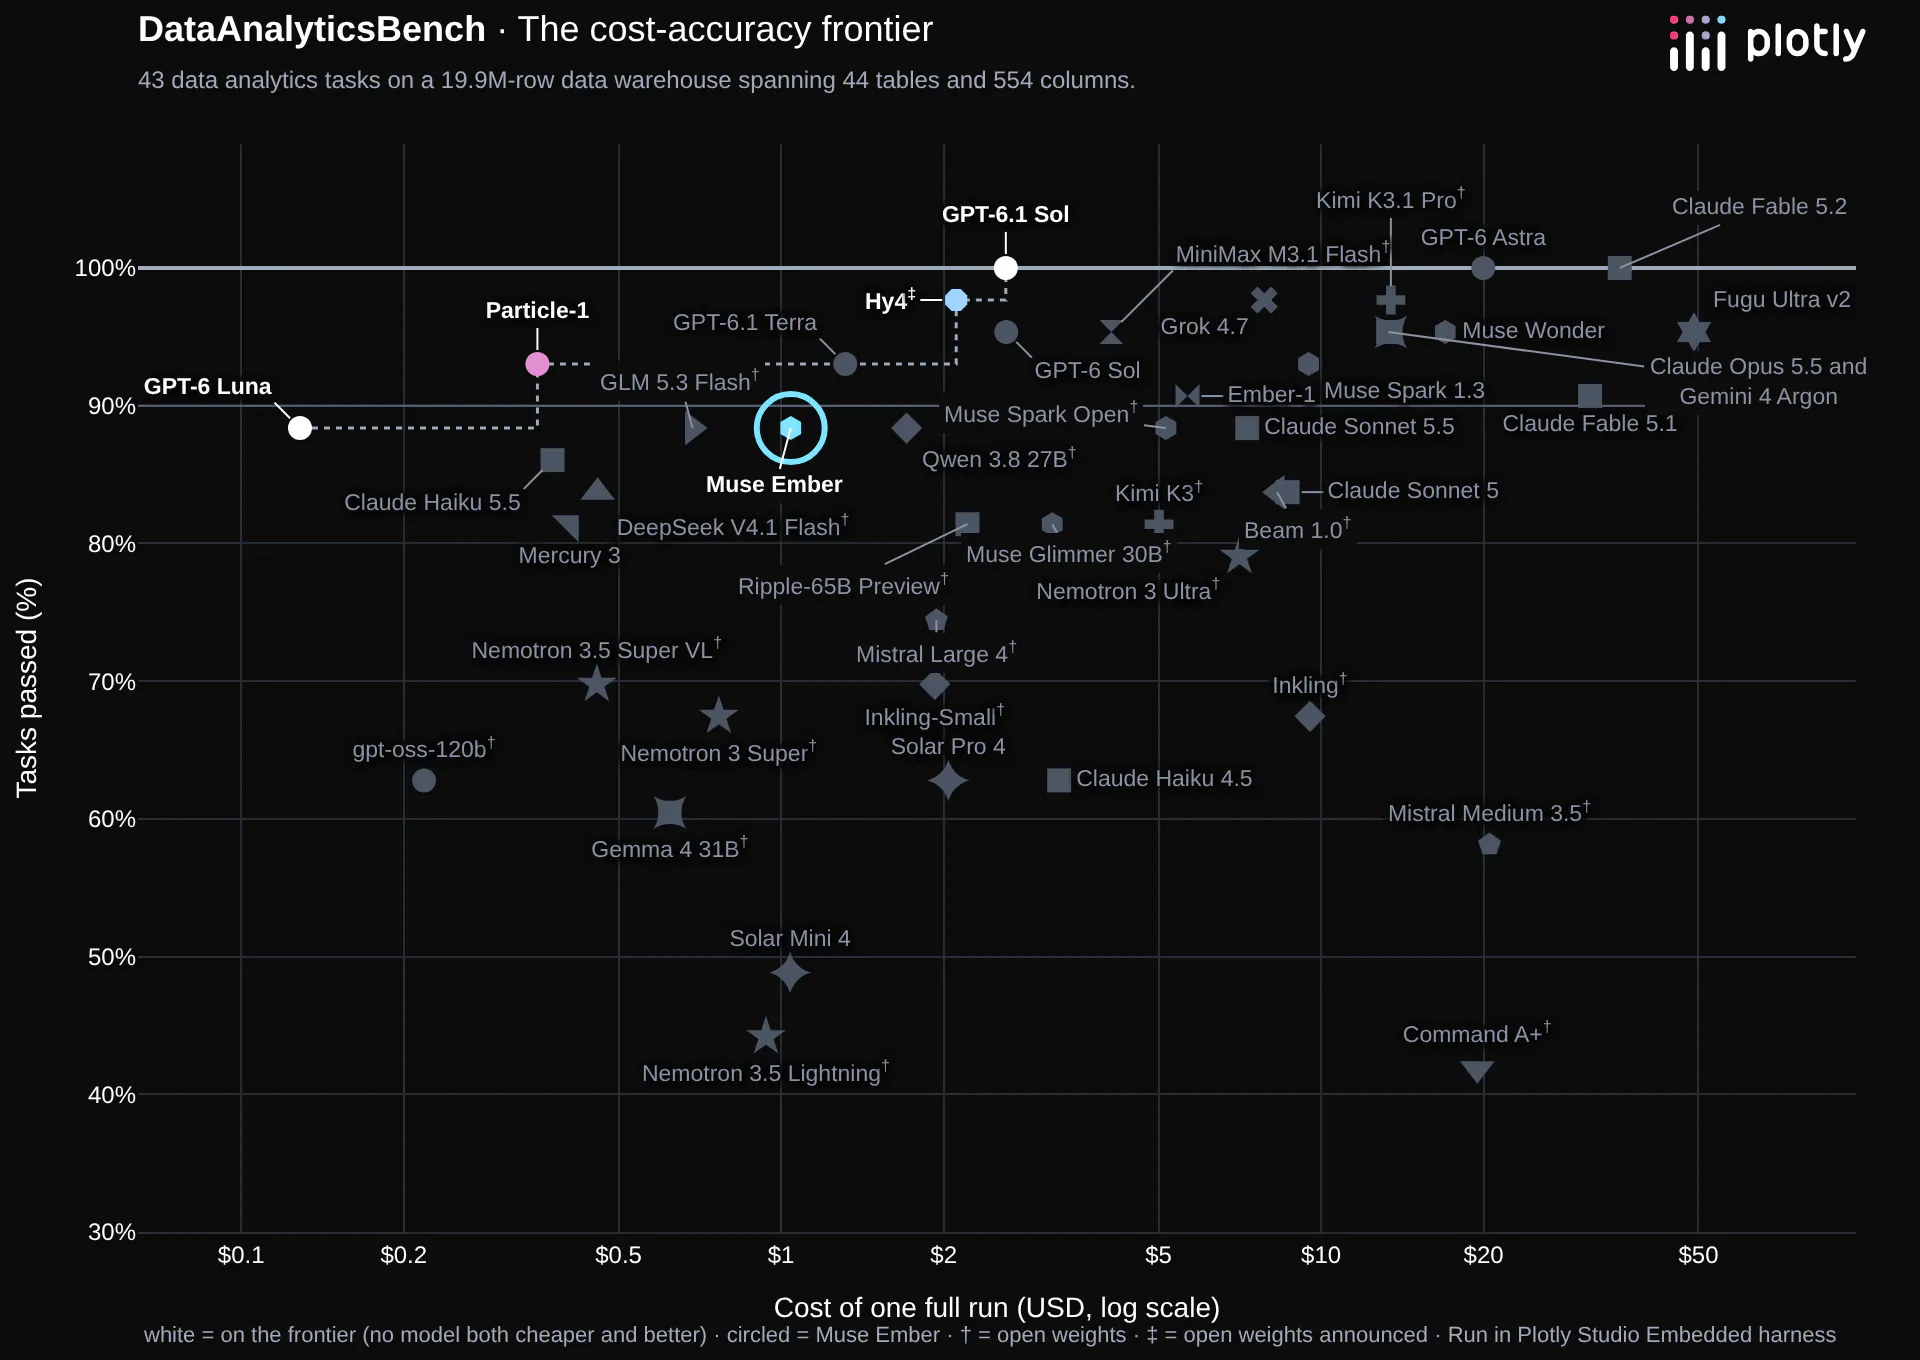
We ran it through our data analytics exam. Muse Ember passed 38 of 43 questions (88%) for $1.04. That ties GPT-6 Luna, beats Claude Haiku 5.5 by a point, and beats Meta's open-weight Muse Glimmer 30B by three points for a third of the cost. On our exam, though, Ember wasn't the cheap option Meta's numbers suggest. It read about 26.6 million tokens, nearly five times as many as GPT-6 Luna, so its run cost eight times as much as Luna's $0.13 for the same score. On the chart below, Ember sits off the frontier.
Muse Ember vs. GPT-6 Luna, Claude Haiku 5.5 and Muse Glimmer 30B
Muse Ember
GPT-6 Luna
Claude Haiku 5.5
Muse Glimmer 30B
Score
38 / 43
38 / 43
37 / 43
35 / 43
Analytics questions
20 / 20
20 / 20
20 / 20
20 / 20
Ambiguous questions
5 / 5
5 / 5
5 / 5
5 / 5
Impossible requests
5 / 5
5 / 5
5 / 5
4 / 5
Data quality
3 / 3
3 / 3
3 / 3
2 / 3
Statistics traps
4 / 5
3 / 5
2 / 5
3 / 5
Hidden needles
1 / 5
2 / 5
2 / 5
1 / 5
Open weights
No
No
No
Yes
Cost of one full run
$1.04
$0.13
$0.38
$3.18
Per person per year*
$61
$7
$22
$185
Median time per question
28 seconds
18 seconds
14 seconds
66 seconds
*1,000 people each asking 10 questions a day, 250 working days a year, at OpenRouter's prices when each model ran.
Ember was perfect on the 33 questions with a clear answer or a clear right move: all 20 analytics questions, all five ambiguous questions, all five impossible requests and all three data quality checks. It caught four of the five statistics traps, more than GPT-6 Luna or Claude Haiku 5.5. It lost almost all of its points on the hidden patterns.
One run per model is a single sample. In our repeat runs of other models, scores moved by up to three points between runs, so treat a one- or two-point gap as close to a tie.
Thorough, and that's where the cost goes
Ember works hard on open-ended questions. On the five questions with hidden patterns it ran 78 queries on average, the second most of the 45 models on our board, where the median is 25. On two of them it ran more than 100. On the questions with a clear answer it was brisk: its median question used 9 queries.
All that querying is what drove up the bill. Ember read about 26.2 million input tokens over the exam, and 70% of them came from the cache at $0.004 per million. Even at Ember's low prices, that volume made our run cost $1.04, against $0.13 for GPT-6 Luna and $0.38 for Claude Haiku 5.5.
Its speed is about average. Ember's median question took 28 seconds, close to the board's median of 27. One question took 75 minutes from start to finish, but almost all of that time went to the database running one heavy query, not to the model, and Ember got that question right. Across all 43 questions, Ember itself spent about 24 minutes generating.
Where it got things wrong
Ember missed five questions.
- Hidden patterns (1 of 5). We hid five patterns in the data, each one something an analyst would want flagged. Ember ran more queries on these questions than almost any model, but it rarely broke the data down along the dimension that showed the pattern. On one, it found the right shortfall, then concluded that nothing explained it without checking the measurement that did. On another, it made a recommendation while noting the field data that pointed against it.
- A statistics trap (4 of 5). On one question it called a set of results unusual without saying what made them unusual. It showed the top of a sorted list instead of setting a threshold.
These misses have the same shape. Ember had plenty of numbers in front of it but didn't always ask the question that would have explained them.
The Test Harness
We run every model in Plotly Studio Embedded, a drop-in analytics agent that runs on Dash apps. This harness is tuned to run data analytics queries and make charts with multi-turn tool calling, with less emphasis on writing text. It's meant to put the data front and center.
Frequently asked questions
How good is Muse Ember at data analysis?
On PlotlyDataAnalyticsBench it passed 38 of 43 questions, tying GPT-6 Luna and one ahead of Claude Haiku 5.5. It was perfect on analytics, ambiguous questions, impossible requests and data quality, but found only one of the five hidden patterns.
How much does Muse Ember cost?
$0.10 per million input tokens, $0.004 per million cached input tokens and $0.50 per million output tokens. Our whole exam cost $1.04, because Ember used many more tokens than similar models. GPT-6 Luna cost $0.13 for the same score.
Is Muse Ember open source?
No. Meta hasn't released the weights. You can use it through Meta's Model API and Muse Code, and through providers such as OpenRouter. Meta's open-weight models are Muse Spark Open and Muse Glimmer 30B, which we cover in our U.S. open-weight models post.
How was Muse Ember trained?
Meta says Ember is the first model it trained using Muse Wonder Full. It hasn't said how many parameters Ember has.
Is Muse Ember better than Muse Glimmer 30B?
On our exam, yes. Ember scored 38 to Glimmer's 35, cost about a third as much ($1.04 against $3.18) and answered in less than half the time. Glimmer's advantage is that its weights are public and small enough to run on a desktop.
About the benchmark
We run new models through the same exam as they're released, and we'll keep sharing what we find. We ran Muse Ember through OpenRouter with the same harness and grading as every other model.
To see all 45 models on one chart and in a full results table, along with cost, speed and how the exam works, see Introducing DataAnalyticsBench.
The exam is private and we're sharing it with researchers. We're keeping it private so that the answer key doesn't make its way into the training set. For the same reason, the data is fabricated: the warehouse is a synthetic wind-energy fleet, built to look like a real operator's data, so its answers don't exist anywhere else.
If you'd like access, reach out to Chris Parmer at Plotly.